Large language models get the headlines, but many of the most valuable AI problems are still best solved with a model trained on your own data: forecasting demand, predicting which customers will leave, spotting fraud, ranking products, inspecting images. Kreatorz is a machine learning development company that builds these models end to end — from checking whether your data can support them, to deploying, monitoring and retraining them in production.
We are pragmatic about technique. Sometimes a well-tuned gradient-boosted model on clean tabular data beats anything more fashionable. Sometimes a pretrained vision or language model fine-tuned on a few thousand examples is the fastest route. And sometimes a generative AI approach is the better fit, in which case we'll say so.
When machine learning beats an LLM
LLMs are general-purpose and excellent with open-ended language. Trained ML models are specialists. A specialist usually wins when:
- The output is a number, score or category — a price, a probability, a risk band, a ranking.
- You need consistency. The same input should produce the same output every time, which matters for audit and regulated decisions.
- Volume is high. Scoring millions of records with a compact model is far cheaper and faster than calling an LLM for each.
- You have labelled history. Past outcomes — sales, churn, defects, approvals — are exactly what supervised learning needs.
- Latency matters. Small models can respond in milliseconds and run on modest hardware or even on a device.
| Custom ML model | LLM (prompted or with RAG) | |
|---|---|---|
| Best output | Scores, forecasts, classes, rankings | Text, summaries, flexible answers |
| Data needed | Historical, labelled examples | Instructions and reference content |
| Cost per prediction | Very low | Higher, grows with usage |
| Consistency | High and testable | Variable, needs evaluation |
| Explainability | Feature importance and clear metrics | Harder to explain |
The two also combine well: an ML model can score and route items while an LLM drafts the explanation or response.
ML development services we offer
Predictive analytics
Forecasting sales, demand, workload or cash flow; predicting churn, conversion, late payment or equipment failure. We deliver predictions where they're used — inside your dashboards, CRM or product — rather than in a spreadsheet nobody opens.
Computer vision development
Image classification, object detection, defect and damage spotting, document and label reading, quality checks on uploaded photos. We use pretrained models as a starting point and fine-tune on your images, with confidence thresholds that send uncertain cases to a person. Our portfolio includes products built around this kind of capability: Checkpoint AI scans purchases with AI and verifies receipts, and Luna offers symptom and image analysis to help pet owners understand what they are seeing.
Natural language processing
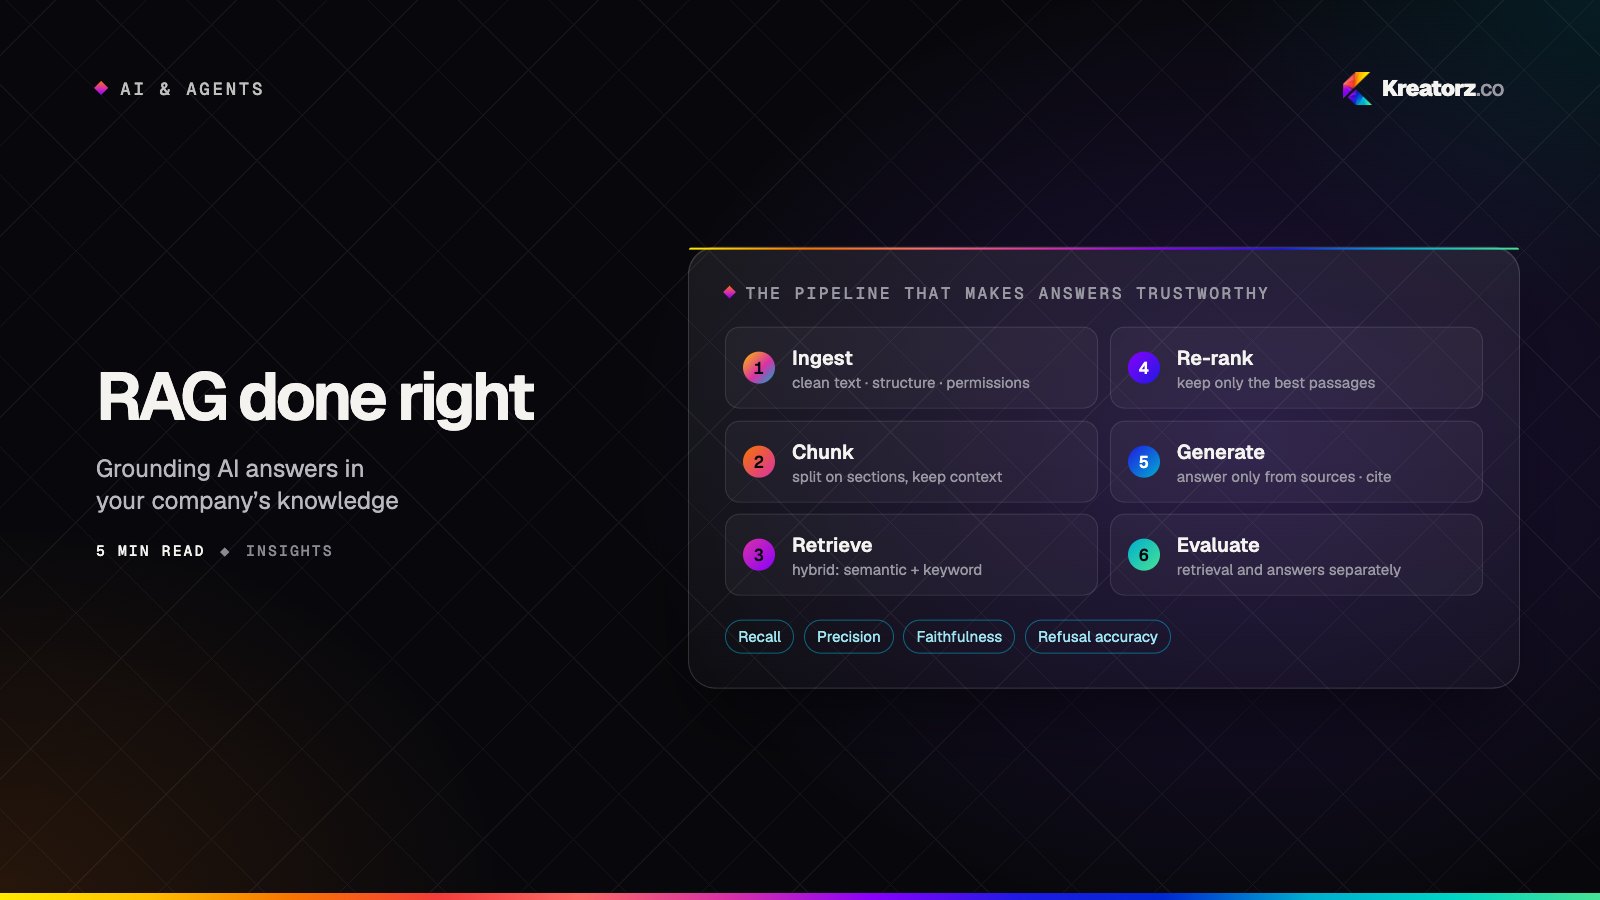
Classifying and routing messages, extracting entities from documents, sentiment and topic analysis, deduplication and semantic search. For many NLP tasks a small fine-tuned model is more reliable and economical than a general LLM; for others, embeddings combined with retrieval work best, as discussed in RAG done right.
Recommendation and ranking
Personalised feeds, product and content recommendations, search ranking and matching — combining behavioural signals with item attributes, and designed to avoid the trap of only recommending what is already popular.
Anomaly detection
Finding unusual transactions, sensor readings, usage spikes or data-quality problems, with alerts tuned so your team isn't drowned in false positives. Spending products such as Checkpoint AI, with its smart blocklist and violation monitoring, show where flagging out-of-pattern activity is useful to families.
Data readiness comes first
Most ML projects are decided by the data before any model is trained. In our first weeks we answer practical questions:
- Is the outcome you want to predict actually recorded? And recorded consistently over time?
- How much history is there, and how representative is it? Seasonal businesses, product changes and policy shifts all affect this.
- Where does the data live? Databases, spreadsheets, third-party tools and legacy systems often need joining; modernising legacy software can be part of the work.
- What are the privacy and consent constraints? We minimise personal data, pseudonymise where possible and keep data in the regions you require.
- Would the predictions be available in time to act on? A churn score that arrives after the customer leaves is useless.
If the data isn't ready, we'll tell you what to start collecting and how, and often recommend a simpler rules-based or LLM-assisted interim solution.
The model lifecycle, step by step
- Frame the decision — what action will the prediction drive, who takes it, and what does a wrong prediction cost in each direction?
- Audit and prepare data — profiling, cleaning, joining sources and building reproducible feature pipelines.
- Establish a baseline — a simple model or existing rule to beat, so improvement is measurable.
- Train and compare models — systematic experiments, tracked and versioned, evaluated on held-out data that mirrors real use.
- Validate with the business — error analysis, fairness checks across relevant groups and review of edge cases with domain experts.
- Deploy — as an API, a batch job or an embedded model, with the Python services and cloud infrastructure to run it reliably.
- Monitor and retrain — tracking data drift, prediction quality and business impact, with scheduled or triggered retraining.
MLOps that keeps models honest
A model starts ageing the day it ships. Customer behaviour shifts, products change, new data sources appear. Our MLOps setup covers versioned datasets and models, automated training pipelines, experiment tracking, staged deployment with rollback, drift and performance monitoring, and audit logs of which model made which prediction. That way retraining is a routine release rather than a rescue project, and you can always explain why a past decision was made.
Why Kreatorz for machine learning development
- AI-native engineering. Kreatorz won the Global AI Impact Award at the Global Image Awards Middle East, Riyadh 2026, and we apply the right technique rather than the trendiest.
- Product-minded data science. Models are built around the decision they support and delivered into the tools people use, including SaaS platforms and mobile apps.
- Full lifecycle. Data engineering, modelling, backend, cloud, QA and monitoring from one team.
- Plays well with agents and LLMs. Our models often feed AI agents and assistants with scores and classifications they can act on.
- Transparent and owned by you. Weekly demos, a shared backlog, and full ownership of code, models, data pipelines and accounts from day one.
- Worldwide reach. Offices in the United States, Canada and Pakistan serving clients across time zones.
Wondering whether your data can support a model? Talk to us and we'll help you find out.